Novogene Korea
  • Novogene Korea
  • Genomics
    • Human Whole Genome Sequencing
    • Plant & Animal Whole Genome Sequencing
    • Microbial Whole Genome Sequencing
    • Whole Exome Sequencing
    • Plant & Animal De novo Sequencing
    • Microbial De novo Sequencing
    • Amplicon Sequencing
    • Shotgun Metagenomics Sequencing
    Transcriptomics
    • mRNA Sequencing
    • Total RNA Sequencing
    • Full-Length Transcriptome Sequencing
    • Whole Transcriptome Sequencing
    • Small RNA Sequencing
    • Circular RNA Sequencing
    • Metatranscriptome Sequencing
    • Prokaryotic RNA Sequencing
    Single Cell & Spatial Omics
    • Single Cell Gene Expression
    • Single Cell Immune Profiling Sequencing
    • Single Cell Long Read Transcriptome
    • Visium HD Spatial Gene Expression
    • Stereo-Seq Spatial Gene Expression
    • Xenium In Situ Spatial Transcriptome
    Epigenomics
    • Whole Genome Bisulfite Sequencing (WGBS)
    • Directed DNA Methylation Sequencing (DM-Seq) NEW
    • Reduced Representation Bisulfite Sequencing (RRBS)
    • Chromatin Immunoprecipitation Sequencing (ChIP-seq)
    • RNA Immunoprecipitation Sequencing (RIP-seq)
    • Assay for Transposase-Accessible Chromatin with Sequencing (ATAC-seq)

    Premade Library

    • Sequencing Only (Illumina 플랫폼)
    • Sequencing Only (PacBio 플랫폼)
    Proteomics & Metabolomics
    • Olink Proteomics
    • Quantitative Proteomics (MS)
    • Untargeted Metabolomics (MS)
  • 프로모션프로모션
    • 플랫폼
    • 자동화 운송 플랫폼 (Falcon)
    • BI 분석툴 (NovoMagic)
    • Customer Service System (CSS)
    • 브로셔
    • 케이스 스터디
    • 웨비나
    • 블로그
    • 샘플준비 가이드라인
    • 커뮤니티
    • 암 연구
    • 면역 종양학
    • 농업
    • 환경
    • 식품
    • 인간 마이크로바이옴
    • 동물 & 식물 마이크로바이옴
    • 신약개발
    • 희귀 질환 연구
    • 회사소개
    • 글로벌 입지
    • 뉴스룸
    • 채용 정보
  • 문의하기문의하기

서비스서비스 menu

고객지원고객지원 menu

기업정보기업정보 menu

서비스
WGSDe novo SeqAmplicon SeqShotgun MetagenomeDM-SeqmRNA-SeqSingle Cell Gene ExpressionVisium HDXenium In SituOlinkUntargeted Metabolomics
고객지원
노보매직CSSFalcon 플랫폼
기업정보
회사소개글로벌 입지플랫폼뉴스룸채용 정보문의하기
LinkedInLinkedIn hoverYouTubeYouTube hoverXX hoverMetaMeta hoverInstagramInstagram hover
Copyright © 2026 Novogene Co., Ltd. All Rights Reserved. 노보진의 한국 내 모든 서비스는 연구 목적 (Research Use Only, RUO) 으로만 제공됩니다. 사업자등록번호: 494-86-03792 | 판매자번호: 노보진코리아유한회사 | 대표자명: 리휘시앙 | 사업자주소: 서울시 강서구 마곡동 779-1번지 뉴브클라우드힐스 BT-230, 231호, 07790 | 전화번호: 02-2038-8036
banner laptop bg
banner mobile bg

Full-Length Transcriptome Seq

전사체 구조, 아이소폼 다양성, 유전자 발현 복잡성을 규명하기 위한 종합적인 전사체 시퀀싱.
견적 요청하기
(Full-Length Transcriptome Seq)
견적 요청하기
(Full-Length Transcriptome Seq)
개요개요
서비스 특징서비스 특징
적용 분야적용 분야
세부사항세부사항
데이터 분석데이터 분석

Full-length transcriptome 시퀀싱은 완전하고 분절되지 않은 mRNA 분자를 포착합니다. 생물정보학적 전사체 조립 과정을 없앰으로써, 이 방법은 새로운 유전자와 아이소폼에 대해 더 포괄적이고 정확한 분석을 제공합니다. 노보진은 다양한 연구 목적에 맞춘 여러 종류의 Full-length transcriptome 솔루션을 제공합니다.


팩바이오 Full-length transcriptome 시퀀싱 (PacBio Iso-Seq): 대체 스플라이싱 사건, gene fusion, 그리고 차등 발현 아이소폼을 높은 정밀도로 특성화할 수 있는 비용 효율적이고 유연한 솔루션입니다.


나노포어 Direct RNA 시퀀싱 (Nanopore): cDNA로 전환하지 않고 mRNA를 원래 형태 그대로 시퀀싱하여 염기 변형(예: m6A, m5C)과 poly(A) tail 특성을 연구합니다.

노보진의 Full-Length Transcriptome Sequencing 서비스: 장점 & 특징

로컬 서포트
로컬 서포트

지역별 기술지원팀과 연구소가 맞춤형이고 신속한 서비스를 제공합니다.

로컬 서포트
로컬 서포트

지역별 기술지원팀과 연구소가 맞춤형이고 신속한 서비스를 제공합니다.

종합 커스텀 솔루션
종합 커스텀 솔루션

복잡한 시료와 까다로운 연구 디자인에 맞추어 유연한 프로젝트를 설계합니다.

종합 커스텀 솔루션
종합 커스텀 솔루션

복잡한 시료와 까다로운 연구 디자인에 맞추어 유연한 프로젝트를 설계합니다.

광범위한 실험 경험
광범위한 실험 경험

300+종에 대한 약 5000여개의 샘플 경험이 있어 신뢰할 수 있고 정교한 워크플로우로 처리합니다.

광범위한 실험 경험
광범위한 실험 경험

300+종에 대한 약 5000여개의 샘플 경험이 있어 신뢰할 수 있고 정교한 워크플로우로 처리합니다.

데이터 퀄리티 보장
데이터 퀄리티 보장

저희 데이터는 제조사의 성능 표시 기준을 넘어서는 퀄리티가 나옵니다.

데이터 퀄리티 보장
데이터 퀄리티 보장

저희 데이터는 제조사의 성능 표시 기준을 넘어서는 퀄리티가 나옵니다.

연구 및 의학 분야에서의 Full-Length Transcriptome Seq. 활용

생의학, 농업, 생명과학 연구에서 발견을 이끌어낼 수 있도록 편향 없는 완전한 RNA 프로파일을 제공합니다.

Novel Transcripts 와 Alternative Splicing 이벤트 발견

새로운 유전자, 아이소폼, 그리고 유전자 융합을 식별하고 특성화한다. 대체 스플라이싱을 종합적으로 분석하여 잠재적인 바이오마커를 밝혀내다.

Novel Transcripts 와 Alternative Splicing 이벤트 발견

새로운 유전자, 아이소폼, 그리고 유전자 융합을 식별하고 특성화한다. 대체 스플라이싱을 종합적으로 분석하여 잠재적인 바이오마커를 밝혀내다.

질병 기전과 약물 내성 해독하기

전체 길이 전사체와 병리학적 상태를 연관 지어 질병의 분자적 기초를 연구합니다. 암과 감염병에서 약물 내성을 유발하는 전사체 수준의 변화를 밝혀내다.

질병 기전과 약물 내성 해독하기

전체 길이 전사체와 병리학적 상태를 연관 지어 질병의 분자적 기초를 연구합니다. 암과 감염병에서 약물 내성을 유발하는 전사체 수준의 변화를 밝혀내다.

고품질 유전체 Annotation 제

진화 및 기능 연구를 지원하기 위해 고품질 유전체 annotation을 활성화합니다.

고품질 유전체 Annotation 제

진화 및 기능 연구를 지원하기 위해 고품질 유전체 annotation을 활성화합니다.

RNA 변형 및 Poly(A) 다이내믹 프로파일링 (Direct RNA 시퀀싱)

핵심 RNA 변형(예: m6A)을 찾아내고, 전사 후 조절을 연구하기 위해 폴리(A) 꼬리 길이를 측정합니다.

RNA 변형 및 Poly(A) 다이내믹 프로파일링 (Direct RNA 시퀀싱)

핵심 RNA 변형(예: m6A)을 찾아내고, 전사 후 조절을 연구하기 위해 폴리(A) 꼬리 길이를 측정합니다.

세부사항

샘플 준비

샘플 양은 참고용으로만 제시되어 있습니다. 자세한 내용은 샘플준비 가이드를 다운로드하여 확인하세요. 자세한 정보가 필요하시면 맞춤 요청을 가지고 저희에게 연락해주세요.

Sample TypeServiceAmount (Qubit)ConcentrationRIN (Agilent 2100)Purity
(NanoDrop™)
TotaI RNAFull-Length Transcriptome Sequencing (PacBio)≥ 1.2 μg≥ 40 ng/μL≥ 6.5 with flat
baseline
OD260/280=1.8-2.2;
OD260/230=1.3-2.5;
*NC/QC ≤ 2.0;
No genomic contamination
TotaI RNANanopore Direct RNA Sequencing≥ 5.5 μg≧ 375 ng/μL≥ 7 (animals, plants, fungi);
≥ 8 (Human)
OD260/280=1.8-2.2;
OD260/230=1.6-2.5;
*NC/QC ≤ 2;
No genomic contamination
Note:
*NC/QC: NanoDrop concentration/Qubit concentration

시퀀싱 & 데이터 분석

권장 데이터 생산량과 표시되는 분석 내용은 참고용일 뿐입니다. 자세한 정보가 필요하시면 맞춤 요청을 가지고 저희에게 연락해주세요.

PlatformFull-Length Transcriptome Sequencing (PacBio)Direct RNA (Nanopore)
Read LengthN50 read length (average) ≥ 1.5 kbN50 read length (average) ≥ 1 kb
Recommended Data Amount• 5 million HiFi reads for highly expressed genes/isoforms detection
• 10 million HiFi reads for moderate/rare genes/isoforms detection
10M~20M reads/sample
(1 PromethION cell/ sample)
Data Analysis Capability• Data QC
• Function Annotation

With reference genome
• Structure analysis
• Alternative splicing
• Alternative polyadenylation
• Novel gene/ Novel transcript prediction and annotation
• Transcription factor analysis
• LncRNA prediction
• Fusion transcript analysis

Without reference genome
• Structure analysis
• Prediction of coding sequences
• Transcription factor analysis
• SSR analysis
• LncRNA prediction

Quantification analysis is available without the aid of short-read mRNA-seq when choosing 10M HiFi reads.
• Gene/ Transcript expression level analysis
• Differentially expressed gene/ transcript analysis
(Transcript analysis can only be conducted when a reference genome is available.)
• Full-length transcripts identification and classification
• Transcript structure analysis
-Alternative splicing
-Novel gene/ Novel transcript prediction and annotation
-Transcription factor analysis
-LncRNA prediction
• Quantification analysis
• Differential gene expression analysis
• GO/KEGG enrichment analysis of differentially expressed genes
• RNA modification analysis
• Poly(A) analysis

*This service is limited to species with a reference genome.

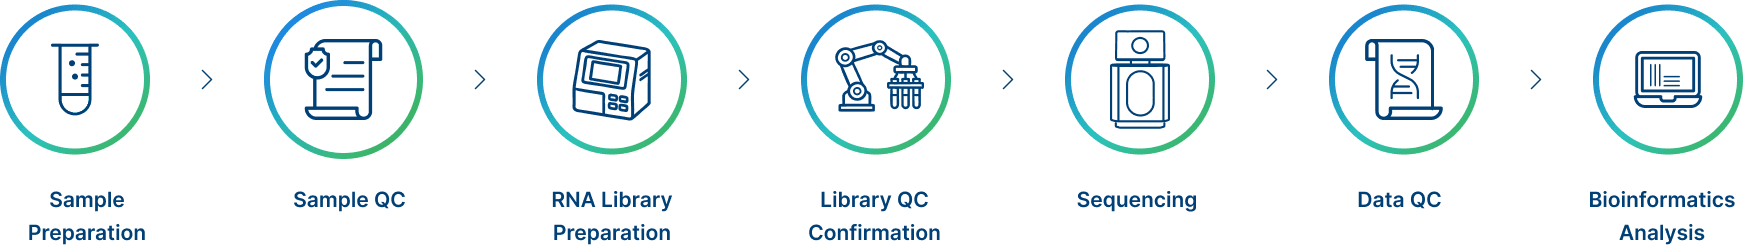
프로젝트 워크플로우

저희의 Full-Length Transcriptome 시퀀싱 워크플로우는 엄격하고 체계적인 과정을 통해 고품질 결과를 보장합니다:

프로젝트 워크플로우

데이터 분석 예시

Image
Image
1/1
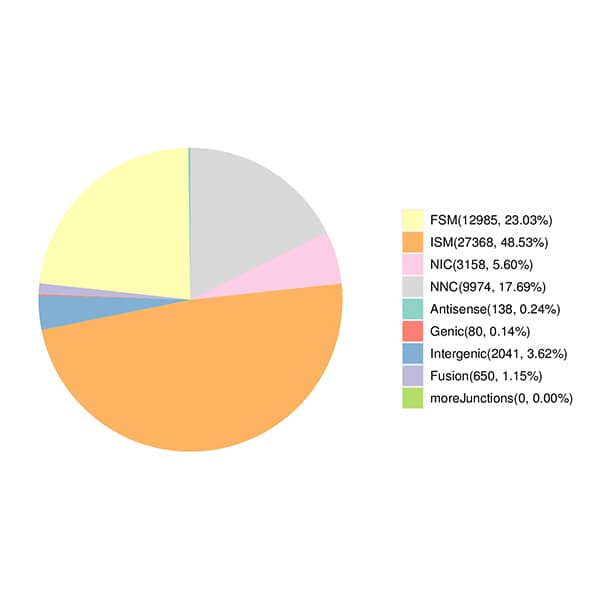
Full-Length Transcripts 분류

원형 차트는 전체 길이 transcript의 분류를 보여줍니다.


Image
Image
1/1
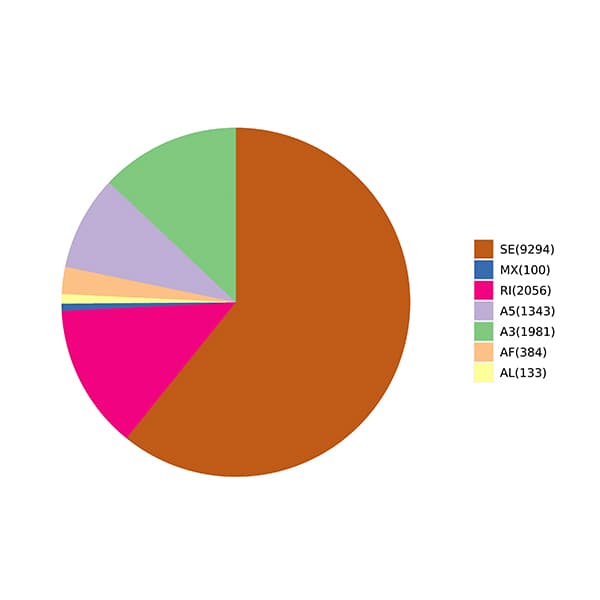
Alternative Splicing

전체 길이 전사체 시퀀싱 데이터로부터 본 대체 스플라이싱 사건 개요

Image
Image
1/1
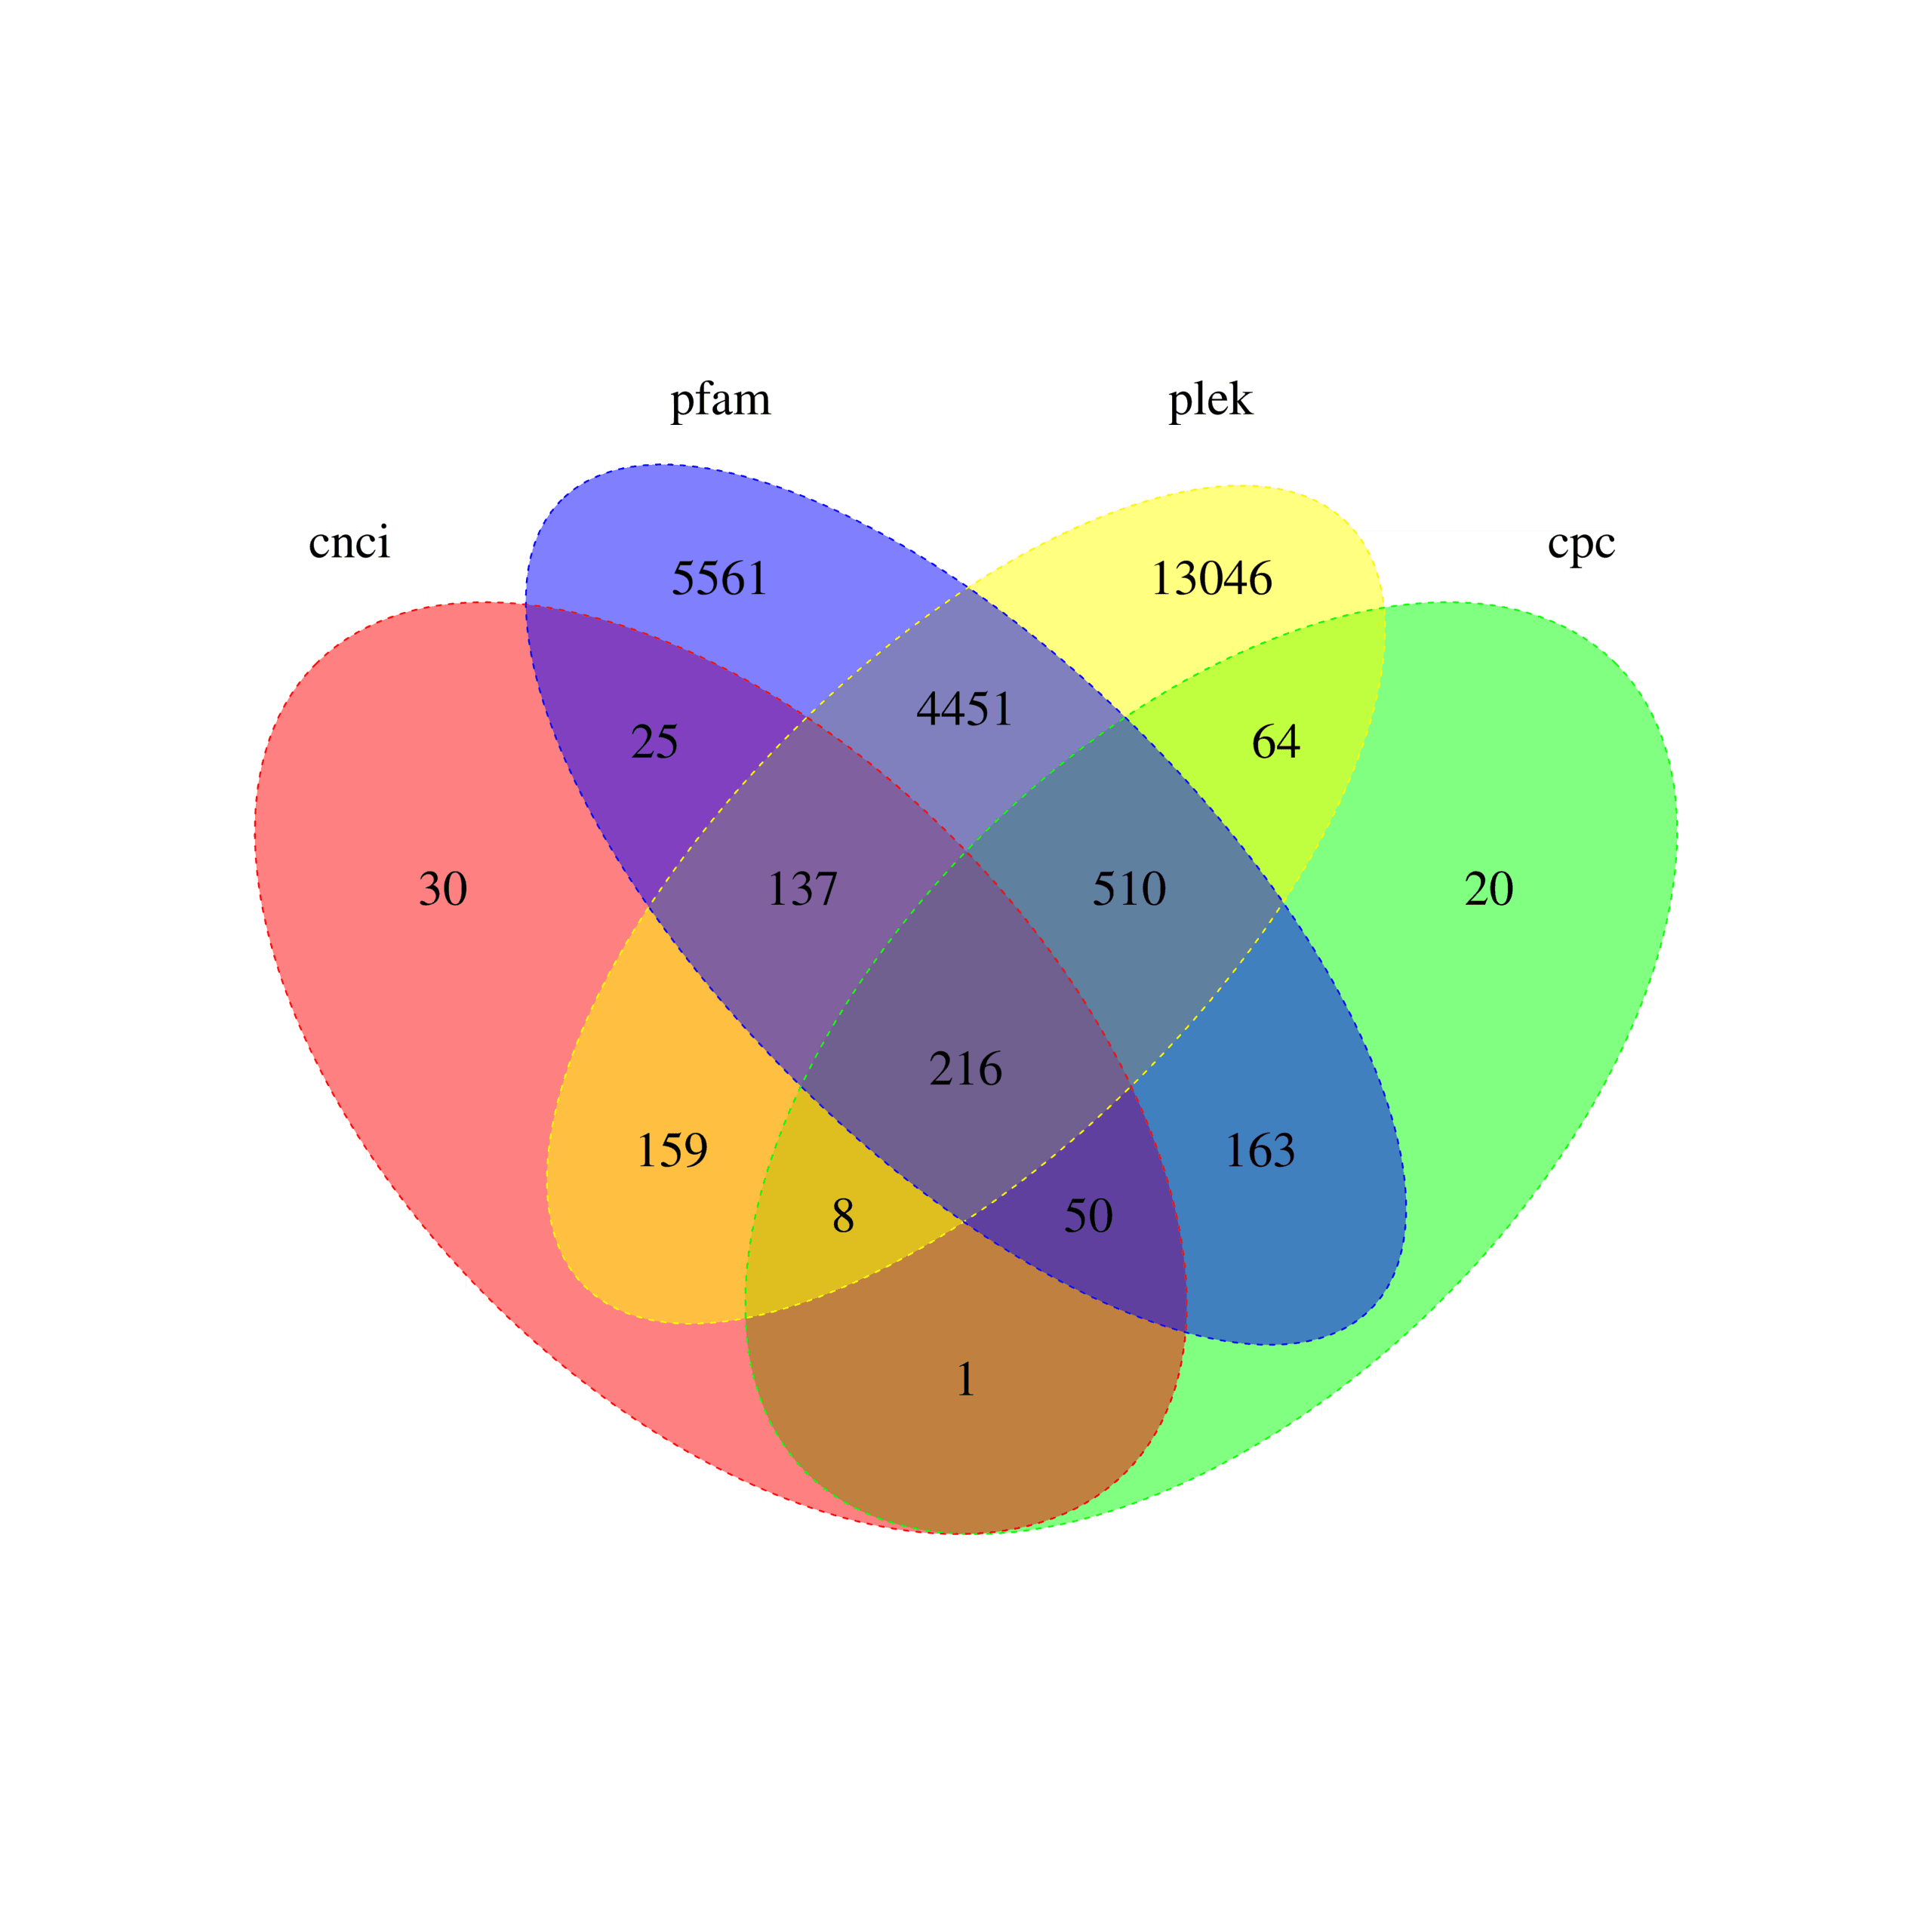
LncRNA 예측과 분석

벤 다이어그램은 여러 도구에서 예측한 비암호화 전사체를 비교하며, 신뢰할 수 있는 후속 분석을 위해 선택된 합의 집합을 강조합니다.

Image
Image
1/1
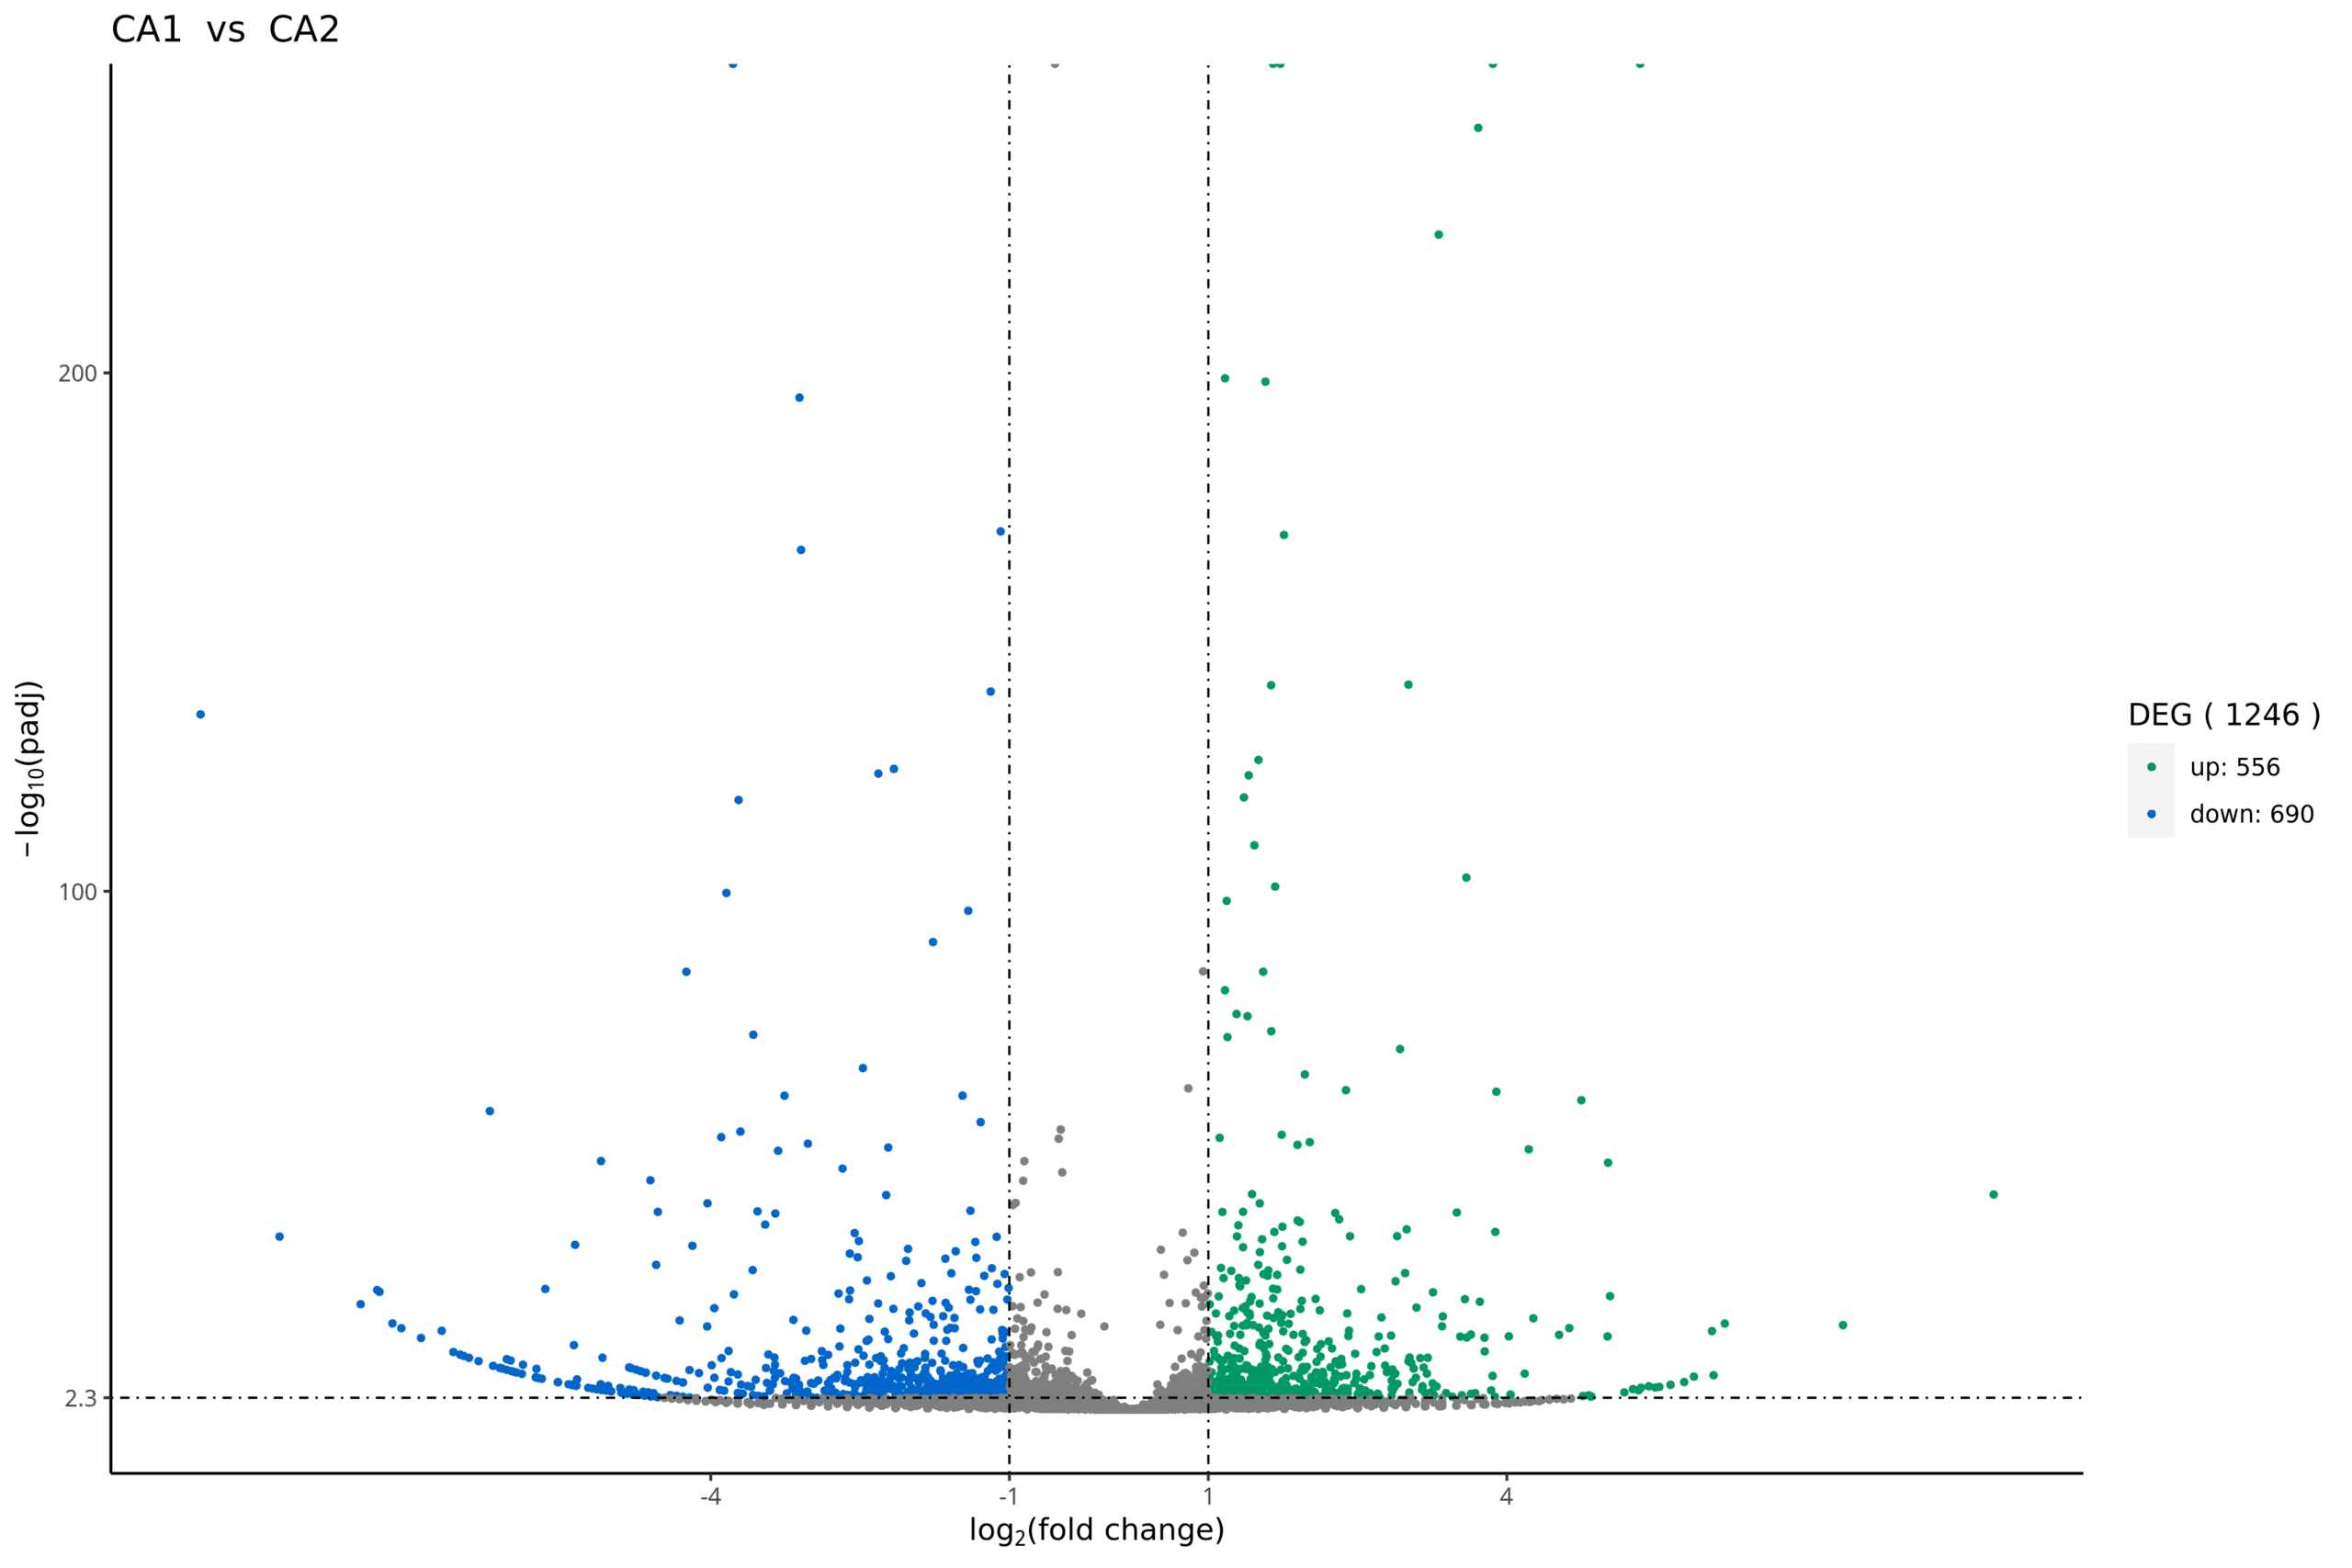
DEG 분석

Volcano plot은 차등 발현 분석 결과를 요약하여, 발현 변화가 뚜렷한 유전자를 즉시 강조합니다.

Image
Image
1/1
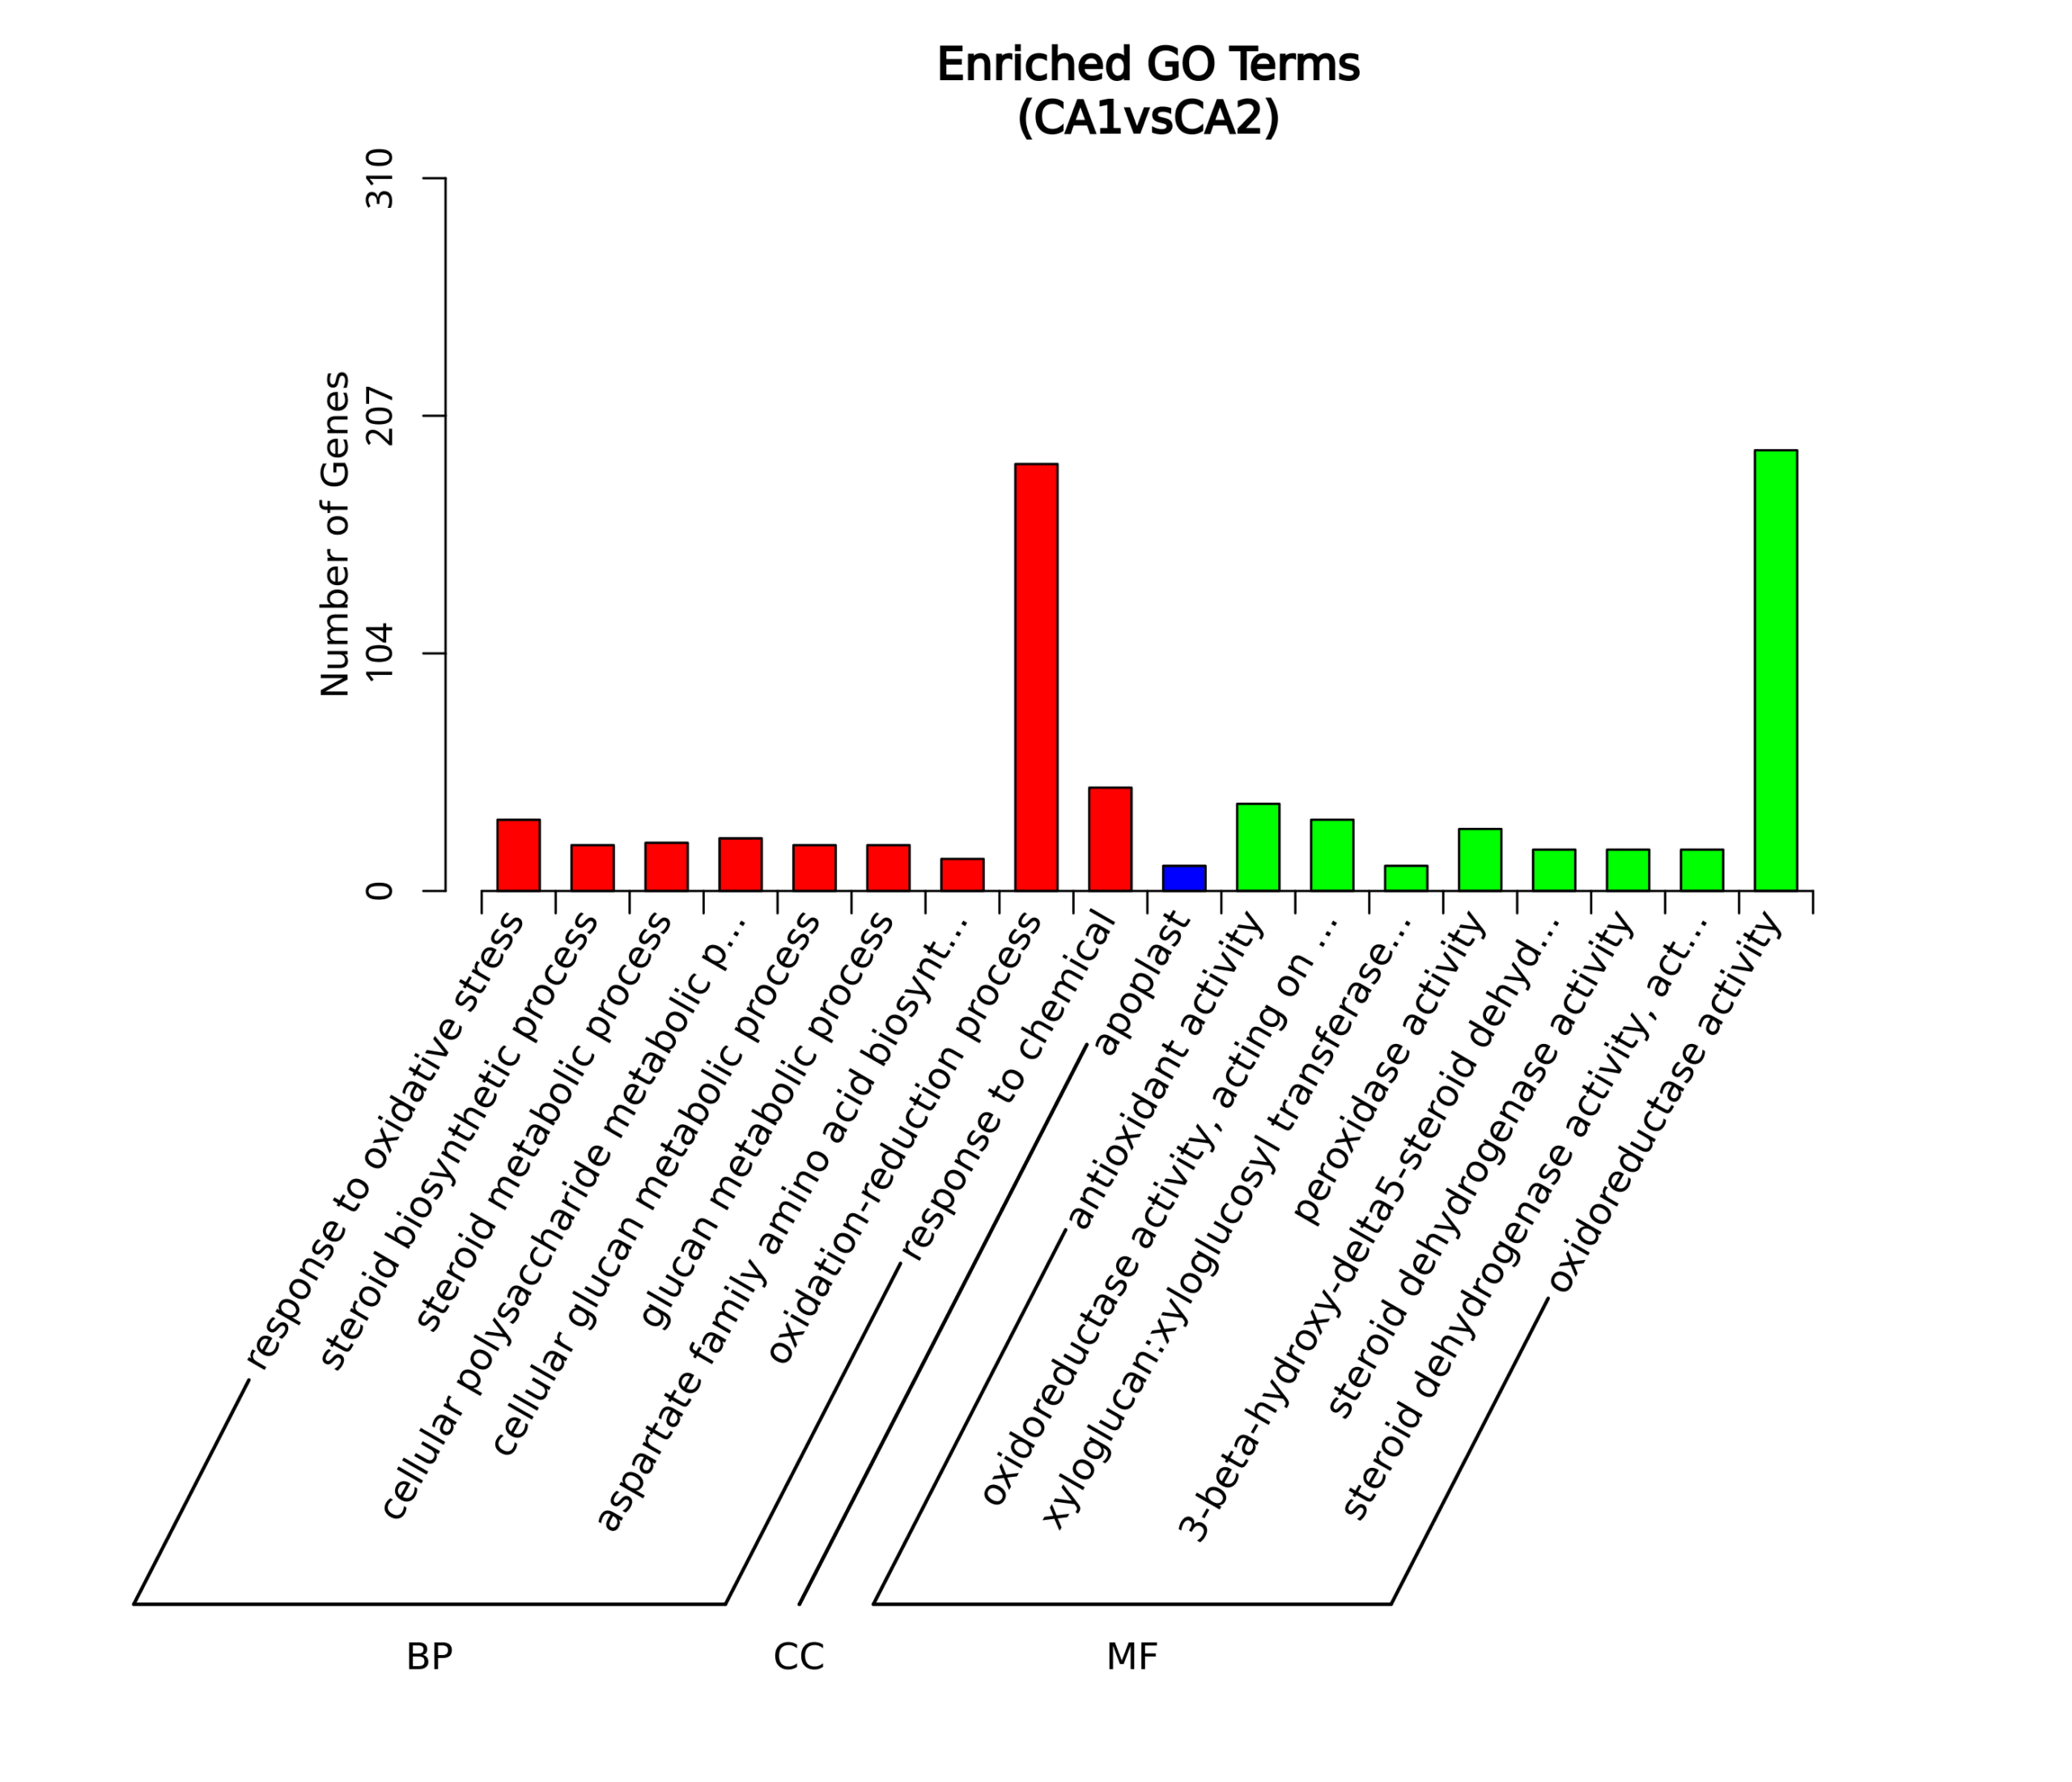
Enrichment 분석 (DEG)

이 막대 그래프는 차등 발현 유전자에 대한 기능적 풍부도 분석에서 가장 유의미하게 풍부한 Gene Ontology 용어들을 보여줍니다.

Image
Image
1/1
Full-Length Transcripts 분류

원형 차트는 전체 길이 transcript의 분류를 보여줍니다.


Image
Image
1/1
Alternative Splicing

전체 길이 전사체 시퀀싱 데이터로부터 본 대체 스플라이싱 사건 개요

Image
Image
1/1
LncRNA 예측과 분석

벤 다이어그램은 여러 도구에서 예측한 비암호화 전사체를 비교하며, 신뢰할 수 있는 후속 분석을 위해 선택된 합의 집합을 강조합니다.

Image
Image
1/1
DEG 분석

Volcano plot은 차등 발현 분석 결과를 요약하여, 발현 변화가 뚜렷한 유전자를 즉시 강조합니다.

Image
Image
1/1
Enrichment 분석 (DEG)

이 막대 그래프는 차등 발현 유전자에 대한 기능적 풍부도 분석에서 가장 유의미하게 풍부한 Gene Ontology 용어들을 보여줍니다.

다른 서비스 탐색

mRNA Sequencing
(mRNA Sequencing)
mRNA Sequencing
(mRNA Sequencing)
Total RNA Sequencing
(Total RNA Sequencing)
Total RNA Sequencing
(Total RNA Sequencing)
Whole Transcriptome Sequencing
(Whole Transcriptome Sequencing)
Whole Transcriptome Sequencing
(Whole Transcriptome Sequencing)

다른 서비스 탐색

mRNA Sequencing
(mRNA Sequencing)
mRNA Sequencing
(mRNA Sequencing)
Total RNA Sequencing
(Total RNA Sequencing)
Total RNA Sequencing
(Total RNA Sequencing)
Whole Transcriptome Sequencing
(Whole Transcriptome Sequencing)
Whole Transcriptome Sequencing
(Whole Transcriptome Sequencing)
Background
Background

국내 담당자의 전문 컨설팅

진행하고자 하는 프로젝트가 있으신가요?

문의 내용을 보내주시면 Novogene 전문가가 연락드리겠습니다.


Privacy PolicyCookie Policy